|
I am currently a Senior Researcher working on generative AI. I obtained my Ph.D. in 2023 from the MMLab at The Chinese University of Hong Kong (CUHK), where I was fortunate to be advised by Prof. Hongsheng Li and Prof. Xiaogang Wang. Prior to that, I earned my bachelor's degree from Nanjing University in 2019. Email / Google Scholar / Github / CV |
|
|
My research spans multimodal models, diffusion models, and computational photography, with a focus on advancing state-of-the-art techniques and addressing real-world challenges. My contributions have been recognized with the SIGGRAPH Asia 2024 Best Paper Award, and most of my publications have been successfully deployed in commercial products. |
|
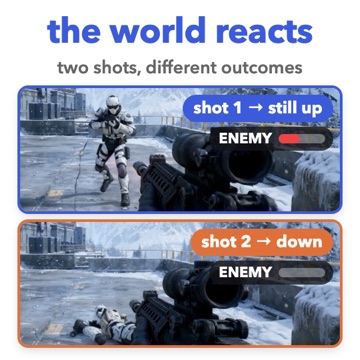
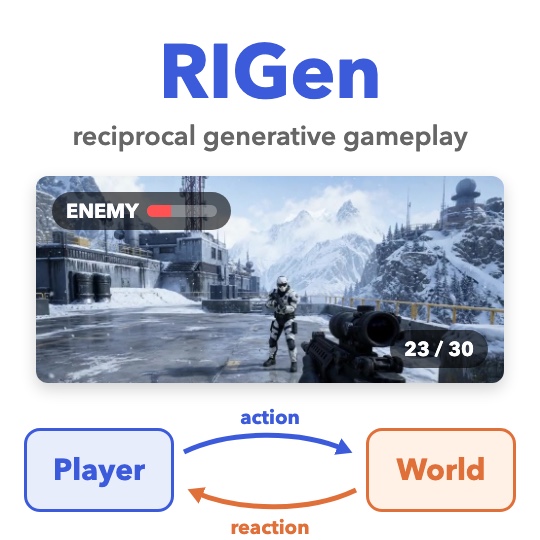
Mengfei Li, Yi Zhang, Xingtong Ge, Lunjie Zhu, Fangyu Lin, Peng Li, Guanglu Song, Yu Liu, Wei Xue, Wenhan Luo, Yike Guo arXiv, 2026 arXiv / project page / code RIGen (Reciprocally Interactive Generation) goes beyond action following in generative gameplay: it combines persistent game state and configurable rules, contextual interaction reasoning, and action-conditioned audio-video generation, so that player actions have lasting consequences and the generated world acts on its own state. Trained on a large Xonotic gameplay dataset, it powers RIGen-Arena, an interactive generative FPS prototype. |
|
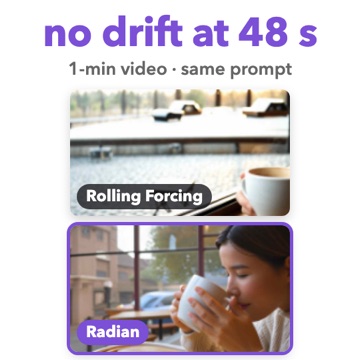
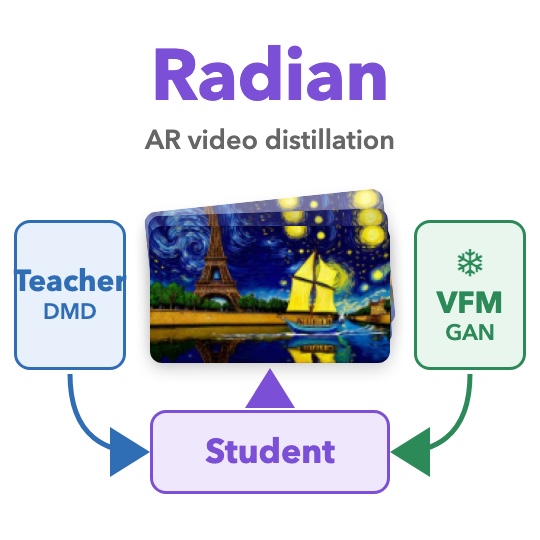
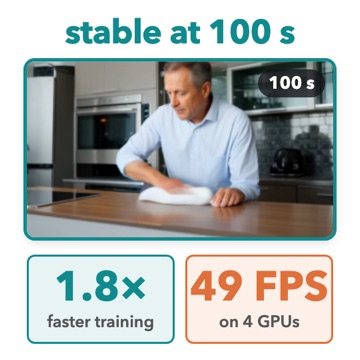
Fangyu Lin, Xingtong Ge, Lunjie Zhu, Yi Zhang, Zhening Liu, Tianhang Wang, Mengfei Li, Yumeng Zhang, Guanglu Song, Yu Liu, Jun Zhang arXiv, 2026 arXiv Radian adds real-data adversarial supervision to on-policy DMD for few-step autoregressive video generation. Discriminator heads operate on frozen visual foundation model features of sparsely decoded rollouts, curbing error accumulation and improving perceptual quality on Wan2.1 for chunk-wise, frame-wise, and minute-long generation at zero extra inference cost. |
|
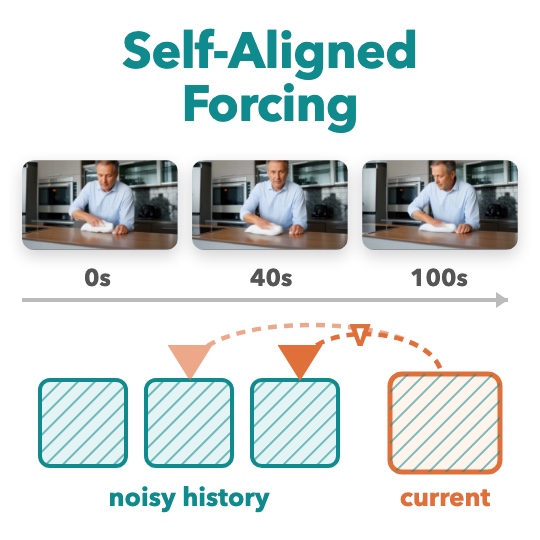
Weiqiang Wang, Zhuokun Chen, Yusheng Dai, Boying Li, Yi Zhang, Hossein Rahmani, Qiuhong Ke, Jianfei Cai arXiv, 2026 arXiv / project page Self-Aligned Forcing aligns each block's K/V history to the noise level of the block being denoised and keeps it differentiable, so a whole denoising stage runs in one causally masked pass. It trains up to 1.8x faster with less memory, reaches 49.1 FPS on 4 GPUs, and better balances visual quality and motion in long-horizon streaming generation. |
|
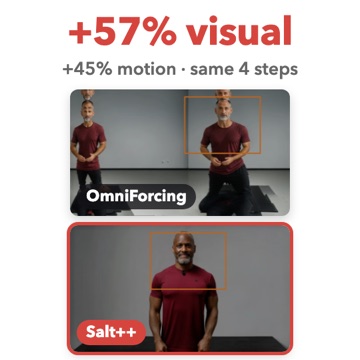
Xingtong Ge, Yutong Wang, Lunjie Zhu, Haitao Lin, Fangyu Lin, Yushi Huang, Xin Zhang, Yi Zhang, Yu Liu, Jun Zhang arXiv, 2026 arXiv / project page Salt++ is a two-stage post-training framework for few-step streaming audio-video generation. Causal Self-Flow supervises contextual representations directly, and context-aligned AR DMD shares one causal context across generator, fake score, and real score. In the same 4-step causal setting it improves visual quality by 57% and motion quality by 45% over OmniForcing, and scales to 4-step 1664×960 generation. |
|
Lunjie Zhu, Xingtong Ge, Fangyu Lin, Yi Zhang, Zhening Liu, Mengfei Li, Yumeng Zhang, Guanglu Song, Yu Liu, Jun Zhang arXiv, 2026 arXiv / code Omni-LiveAvatar is the first framework for minute-level, real-time streaming joint audio-video avatar generation. It distills a bidirectional audio-video diffusion teacher (LTX-2) into a few-step autoregressive generator, with synchronized long-short-term memory and hierarchical rolling prompt planning, achieving a 33× speedup on a single H200. |
|
Xingtong Ge, Yi Zhang, Yushi Huang, Dailan He, Xiahong Wang, Bingqi Ma, Guanglu Song, Yu Liu, Jun Zhang ECCV, 2026 arXiv / project page Salt distills video generators down to 2–4 NFEs by combining Self-Consistent Distribution Matching Distillation (SC-DMD) with Cache-Distribution-Aware training, treating the KV cache as a quality-parameterized condition. It improves low-NFE quality on both non-autoregressive (Wan 2.1) and real-time autoregressive (Self-Forcing) backbones. |
|
|
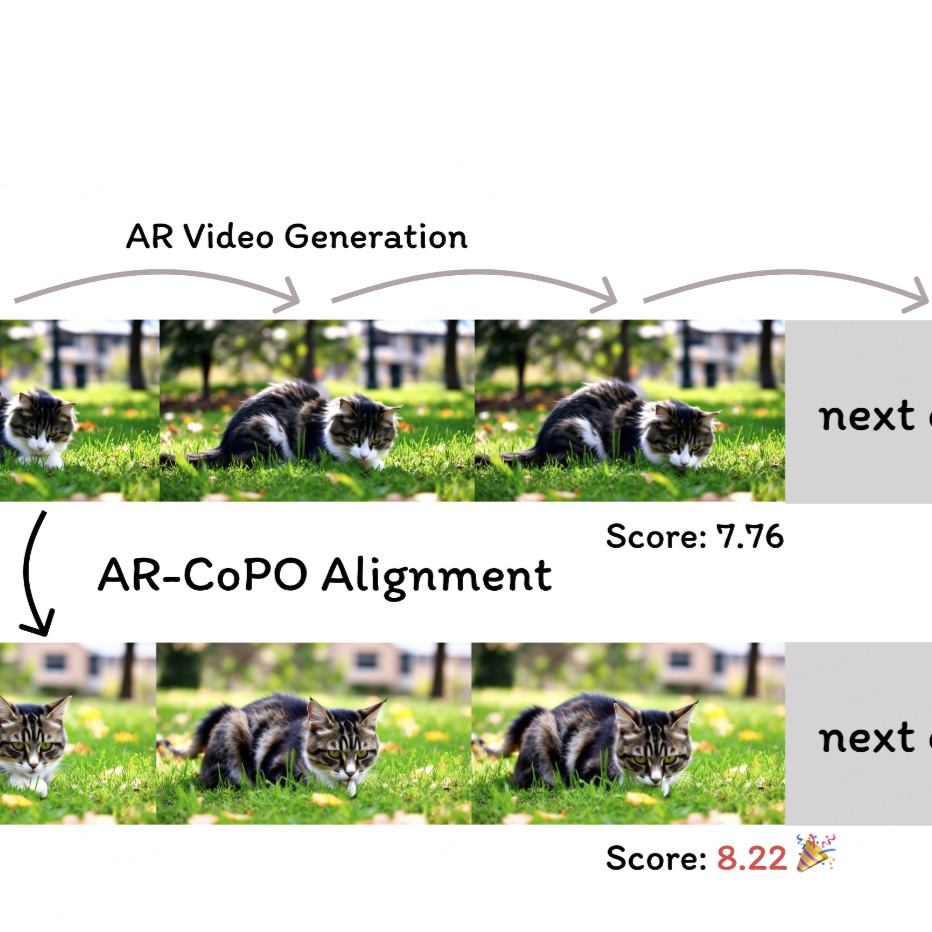
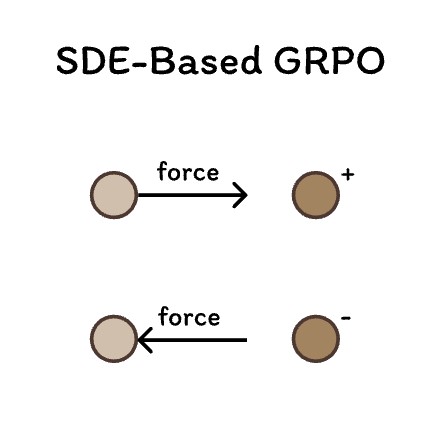
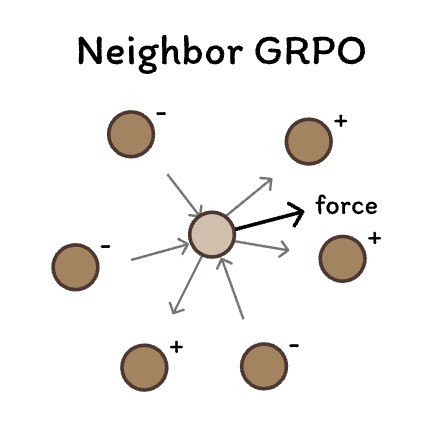
Dailan He, Guanlin Feng, Xingtong Ge, Yi Zhang, Bingqi Ma, Guanglu Song, Yu Liu, Hongsheng Li ECCV, 2026 arXiv AR-CoPO adapts Neighbor GRPO to few-step streaming autoregressive video generators. By forking neighborhood candidates at a randomly chosen chunk and blending on-policy exploration with a replay buffer of reference rollouts, it delivers genuine RLHF alignment gains on Self-Forcing without falling into reward hacking. |
|
Dailan He, Guanlin Feng, Xingtong Ge, Yazhe Niu, Yi Zhang, Bingqi Ma, Guanglu Song, Yu Liu, Hongsheng Li CVPR, 2026 arXiv Neighbor GRPO enables GRPO for flow matching models by bypassing SDEs entirely. By reinterpreting SDE-based GRPO from a distance optimization perspective, we generate diverse trajectories via perturbed initial noise and optimize using a distance-based surrogate policy, preserving ODE efficiency while outperforming SDE-based methods. |
|
Yunpeng Liu, Xingzhong Hou, Jie Wu, Boxiao Liu, Yi Zhang, Guanglu Song, Yu Liu, Changyao Tian, Gen Luo, Haihang You CVPR, 2026 arXiv We propose Blend-Aware Latent Diffusion (BlendRecon + BlendGen ) to address boundary discontinuity and content inconsistency in diffusion-based inpainting, mitigating stitched seams and improving quality. |
|
Xingtong Ge, Xin Zhang, Tongda Xu, Yi Zhang, Xinjie Zhang, Yan Wang, Jun Zhang ICLR, 2026 arXiv / huggingface / code We address convergence difficulties of Distribution Matching Distillation (DMD) on large-scale flow-based models. By proposing implicit distribution alignment (IDA) and intra-segment guidance (ISG), SenseFlow enables DMD to converge for SD 3.5 and FLUX.1 dev, achieving superior distillation performance for both diffusion and flow-matching models. |
|
Yunpeng Liu, Boxiao Liu, Yi Zhang, Xingzhong Hou, Guanglu Song, Yu Liu, Haihang You CVPR, 2025 arXiv / supplement The study introduces the Curriculum Consistency Model (CCM) to address inconsistent learning complexity in Consistency Distillation for diffusion and flow models, balancing complexity via a PSNR-based curriculum. |
|
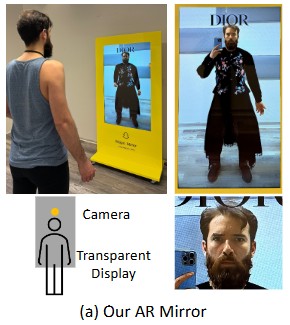
Jian Wang, Sizhuo Ma, Karl Bayer, Yi Zhang, Peihao Wang, Bing Zhou, Shree Nayar, Gurunandan Krishnan SIGGRAPH Asia, 2024, (Journal) (Best Paper Award) arXiv / supplement / code A novel AR mirror system that allows a seamless, perspective-aligned user experience, which is enabled by placing the camera behind a transparent display. |
|
Xiaoyu Shi, Zhaoyang Huang, Fu-Yun Wang, Weikang Bian, Dasong Li, Yi Zhang, Manyuan Zhang, Ka Chun Cheung, Simon See, Honwei Qin, Jifeng Dai, Hongsheng Li SIGGRAPH, 2024 arXiv / code We introduce Motion-I2V, a novel framework for consistent and controllable image-to-video generation (I2V). In contrast to previous methods that directly learn the complicated image-to-video mapping, Motion-I2V factorizes I2V into two stages with explicit motion modeling. |
|
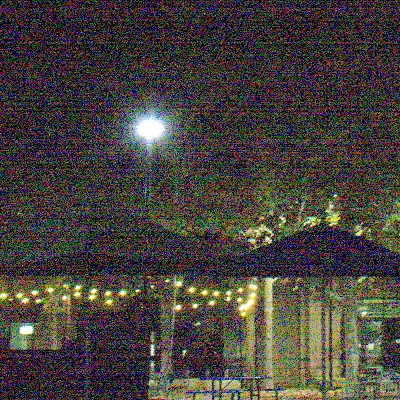
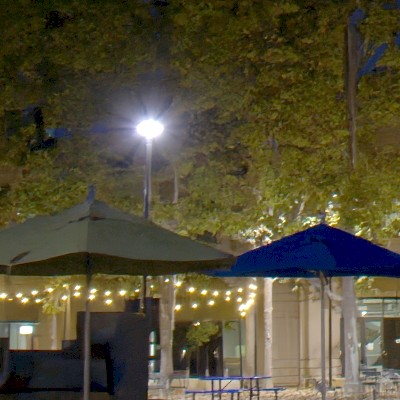
Yi Zhang, Xiaoyu Shi, Dasong Li, Xiaogang Wang, Jian Wang, Hongsheng Li NeurIPS, 2023 arXiv / code / project A unified conditional framework based on diffusion models for image restoration. |
|
Yi Zhang, Dasong Li, Xiaoyu Shi, Dailan He, Kangning Song, Xiaogang Wang, Honwei Qin, Hongsheng Li Arxiv, 2023 arXiv / code A general-purpose backbone for image restoration tasks (e.g. denoising, deraining, and deblurring). A novel kernel basis attention (KBA) module has been proposed to effectively aggregate the spatial information via a series of learnable kernel bases. |
|
Dasong Li, Xiaoyu Shi, Yi Zhang, Xiaogang Wang, Honwei Qin, Hongsheng Li CVPR, 2023 arXiv / code / project We propose a grouped spatial-temporal shift module for effective video restoration. It surpasses previous SOTA methods with only 43% computational cost on video deblurring and denoising. |
|
Dasong Li*, Yi Zhang*, Ka Lung Law, Xiaogang Wang, Honwei Qin, Hongsheng Li IJCV, 2022 arXiv A practical low-light imaging system for burst raw image denoising. It has been deployed to some commercial smartphones. |
|
Dasong Li, Yi Zhang, Ka Chun Cheung, Xiaogang Wang, Honwei Qin, Hongsheng Li ECCV, 2022 arXiv / code Learning degradation representations for blurry images. The learned degradation representation shows pleasing improvements on both image deblurring and reblurring. |
|
Yi Zhang, Dasong Li, Ka Lung Law, Xiaogang Wang, Honwei Qin, Hongsheng Li CVPR, 2022 arXiv / code / SenseNoise dataset A self-supervised image denoising method using noisy images and the noise model. We achieve SOTA results on both real-world noise and synthetic noises (both point-wise and spatial correlated noise types). |
|
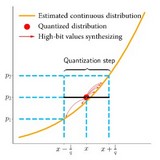
Yi Zhang, Honwei Qin, Xiaogang Wang, Hongsheng Li ICCV, 2021 arXiv / code A method to synthesize "almost the most realistic" raw image noise by sampling directly from the real noise distribution. We also found existing comparisons of noise synthesis methods are based on inaccurate noise parameters. |
|
|
Zhen-Jia Pang, Ruo-Ze Liu, Zhou-Yu Meng, Yi Zhang, Yang Yu, Tong Lu AAAI, 2019 (Oral) arXiv / demo We achieve over 93% winning rate of Protoss against the most difficult non-cheating built-in AI (level-7) of Terran, training within two days using a single machine with only 48 CPU cores and 8 K40 GPUs. |
|
|
|
|
|
|
|
The website template was borrowed from here.
|